
AIMAC: The AI Model Accessibility Checker
AI is writing more code than ever. But is it accessible to People with Disabilities?
We prompted the top AI models to build web pages across 28 categories and audited them for accessibility. We published every generated page, side by side, so you can see how different models tackle the same design.
Leaderboard










Analysis
Audit correction, November 12, 2026. We fixed two bugs that affected earlier scores. Some saved pages were cut off early, and our audits missed some pages where content was revealed by scrolling. We re-audited 1,988 saved pages.
Introduction
95.9% of the top million home pages fail basic accessibility checks. WebAIM has tracked it since 2019. After years of slow improvement, the failure rate rose in 2026, up from 94.8% in 2025. Average errors per page increased 10.1% to 56.1.
WebAIM names AI-assisted coding among the likely contributors to the decline. In JetBrains' May to July 2026 survey of more than 15,000 professional developers, respondents estimated that about 47% of their code at work was generated entirely by AI agents. If AI keeps writing code as poorly as the developers it learned from, nothing changes. But if it prioritizes accessibility, the web gets its first real chance to improve.
Our one ambitious goal
Ensure that AI models write accessible code by default.
Which Model is Best?
GPT 5.4 Mini by OpenAI is #1 on AIMAC. It achieves a median AIMAC Debt of 0.00 for $0.89 across all 28 categories, with 19 total accessibility violations. Its average debt is 0.81.

The Pareto Frontier
AIMAC Debt vs Cost
Choosing a model isn't simply about which model is most accessible. Some models are very expensive. Benchmarks commonly use Pareto Frontier analysis to compare models on quality vs cost dimensions. Pareto optimal models (teal diamonds) are the efficient picks: to lower the AIMAC Debt grade, you'd pay more; to pay less, your AIMAC Debt grade rises. An amber ring marks the lowest AIMAC Debt.
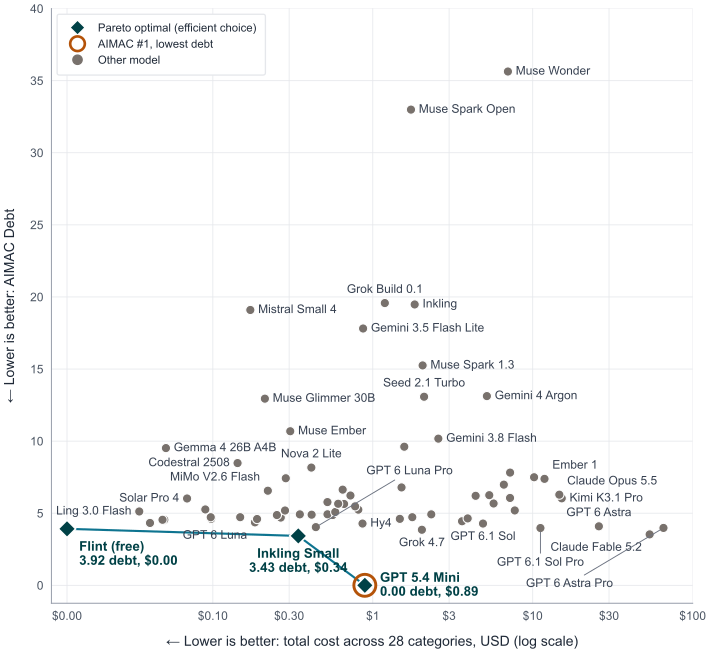
Pareto optimal: Flint (free), 3.92 debt at no cost; Inkling Small, 3.43 debt for $0.34; GPT 5.4 Mini, 0.00 debt for $0.89. Unlabeled dots appear by name in the leaderboard.
Top 3 Winners
-
OpenAI -
Thinking Machines -

Anthropic
1. OpenAI takes first place with GPT 5.4 Mini, which achieves median AIMAC Debt of 0.00 across 28 categories.
OpenAI's GPT 6.1 Sol Pro ranks #6 with median AIMAC Debt of 3.97, ahead of GPT 6.1 Sol at #11 with 4.28. GPT 6.1 Terra Pro ranks #14 with debt of 4.44, while GPT 6.1 Terra ranks #18 with 4.61.
2. Thinking Machines takes second place with Inkling Small, which achieves median AIMAC Debt of 3.43.
3. Anthropic's Claude Fable 5.2 ranks #3 with AIMAC Debt of 3.53.
Claude's Accessibility Breakthrough
Fable 5.2 takes third place out of 72 models.
It leads Anthropic's current models on AIMAC.
Fable 5.2 has median AIMAC Debt of 3.53 and 228 accessibility violations across 28 categories. We've been disappointed in Claude's accessibility results. We're happy to see Fable turn things around. This bodes well for the future of accessibility.
Among the other Claude models, Haiku 5.5 ranks #29 with debt of 4.92, Sonnet 5.5 ranks #34 with 5.19, and Opus 5.5 ranks #48 with 6.29.
We previously raised concerns about accessibility in Anthropic's frontend-design skill. We're happy to see its September 2 update ask for visible keyboard focus, reduced motion and visually accessible color palettes.
Google's Model Mix
 Gemma 4 31B is Google's highest-ranked model at #17 of 72,
with median AIMAC Debt of 4.60.
Gemini 4 Hydrogen enters at #47 with median AIMAC Debt of 6.25. It is the highest-ranked Gemini model in this benchmark.
Gemini 4 Carbon debuts at #56 with AIMAC Debt of 7.82. Gemma 4 26B A4B ranks #59 with debt of 9.52, followed by Gemini 3.8 Flash at #61 with 10.17.
Gemini 4 Argon ranks #65 with AIMAC Debt of 13.12. Gemini 3.5 Flash Lite ranks #67 with debt of 17.81.
Beyond the Rankings
As AI models get better at visual design, they face a tradeoff between optimizing for beauty or for accessibility. You can achieve both, but it requires deliberate effort.
If you're picking a model for your workflow, start with a category page that matches your use case. Each category shows how 72 models handled the same category, alongside their AIMAC Debt. For example, visit the Sports category in grid mode to compare sports designs side by side.
If you already have a model in mind, use the model detail page to see what its pages look like across all 28 categories. Then drill down into the categories that match your needs. See Kimi K3.1 Pro in grid mode for an example.
Newcomers
Particle AI's Particle 1 ranks #27 with debt of 4.90.
Ricursive's Ripple 65B Preview ranks #54 with AIMAC Debt of 7.43.
Value vs Premium
Closed vs Open (Source/Weights)
A closed model holds the top spot. GPT 5.4 Mini (proprietary) ranks #1. Open-weight entries include Inkling Small at #2, Recursive's Flint at #5, Nex N2.6 at #33, GLM 5.3 Flash at #35, and Kimi K3.1 Pro at #43. OpenAI's gpt oss 120b ranks #22 with median debt of 4.72. Weights for GLM 5.3 Flash are publicly available.
More Model Results
China-based labs account for 26 of the 72 models: ByteDance Seed, Qwen, Z.ai, DeepSeek, MiniMax, MoonshotAI, Tencent, Xiaomi, StepFun, Meituan, Ant Group's inclusionAI, and Nex AGI. Tencent, Xiaomi, StepFun, Meituan, and inclusionAI joined in July 2026, and Meituan says LongCat 2.0 was trained and served entirely on Chinese-made chips. Despite US chip restrictions, Chinese labs keep shipping.
MoonshotAI describes Kimi K3.1 Pro as a model built for long coding tasks and agent workflows. In AIMAC, K3.1 Pro ranks #43 with debt of 6.03, while MoonshotAI's Kimi K2.7 Code ranks #20 with debt of 4.64.
DeepSeek's September 10 release announcement lists OpenCode and CodeBuddy support for V4.1 Flash, connecting it directly to everyday coding workflows. In AIMAC, V4.1 Flash 1017 ranks #21 with debt of 4.70, while V4 Pro 0813 ranks #28 with debt of 4.92.
Mistral's Large 4 is its best result at #55 with a debt of 7.50. Codestral 2508 ranks #58, Medium 3.5 ranks #60 with debt of 9.61, and Mistral Small 4 ranks #68 with debt of 19.10.
Meta's Muse Ember debuts at #62 with AIMAC Debt of 10.69. Muse Spark Open and Muse Wonder finish at the bottom. Muse Spark Open ranks #71 of 72 with AIMAC Debt of 32.99, and Muse Wonder ranks #72 with debt of 35.63. The audits recorded 1,248 and 1,506 accessibility violations respectively across 28 categories.
What Trips Models Up
In this leaderboard, low contrast text accounts for 90.3% of detected errors across 2,016 generated pages. In WebAIM Million 2026, low contrast text makes up about 61% of all errors found on real-world home pages. Missing alt text, unlabeled form fields and unnamed buttons affect a smaller share of AIMAC pages. Other accessibility errors still appear on 45.7% of AIMAC pages.
The lists below show how widespread each problem is: the percentage of pages with at least one instance. AIMAC tests AI-generated pages with axe-core. WebAIM tests the top one million home pages with WAVE. Different tools and page samples limit how directly these results can be compared.
AIMAC: Top 6 issues
Share of pages with at least one error
- Low contrast text: 90.9%
- Missing form labels: 16.5%
- Empty links: 14.0%
- Target size too small: 10.0%
- Certain ARIA roles must contain particular children: 5.3%
- Links distinguished only by color: 4.5%
WebAIM Million 2026: Top 6 issues
Share of home pages with at least one error
- Low contrast text: 83.9%
- Missing alt text: 53.1%
- Missing form labels: 51.0%
- Empty links: 46.3%
- Empty buttons: 30.6%
- Missing document language: 13.5%
Emdash Benchmark
We tracked emdash usage as a small writing-style signal, because punctuation can affect how text is read aloud.
Screen readers handle emdashes differently. Some announce "em dash" at every occurrence, others treat it as a pause, and some ignore it depending on voice and settings. Ricky Onsman explored the issue and found this is largely a screen reader behavior difference, not a content authoring bug.
We sanity-checked this with screen reader users, and none of our friends reported emdash-heavy text as a practical problem in day-to-day reading. So this turned out to be more interesting than impactful, and it does not affect AIMAC rankings.
Emdash usage varies widely. Across 72 models, counts range from 0 (Codestral 2508) to 1899 (GLM 5.3 Flash). 2 models use zero emdashes.
View emdash leaderboard (72 models)
| Rank | Model | Emdash Count |
|---|---|---|
| 1 | Codestral 2508 Mistral | 0 |
| 2 | Nova 2 Lite Amazon | 0 |
| 3 | Mistral Medium 3.5 Mistral | 3 |
| 4 | Claude Haiku 5.5 Anthropic | 4 |
| 5 | GLM 4.7 Flash Z.ai | 8 |
| 6 | Mistral Small 4 Mistral | 18 |
| 7 | Gemma 4 26B A4B Google | 20 |
| 8 | Gemma 4 31B Google | 21 |
| 9 | Gemini 3.5 Flash Lite Google | 22 |
| 10 | Nemotron 3.5 Lightning NVIDIA | 26 |
| 11 | Solar Mini 4 Upstage | 29 |
| 12 | Nemotron 3.5 Super VL NVIDIA | 40 |
| 13 | Flint (free) Recursive | 48 |
| 14 | gpt oss 120b OpenAI | 54 |
| 15 | Gemini 3.8 Flash Google | 55 |
| 16 | Grok Build 0.1 SpaceXAI | 61 |
| 17 | GPT 6.1 Terra Pro OpenAI | 67 |
| 18 | GPT 6.1 Terra OpenAI | 73 |
| 19 | Hy4 Tencent | 78 |
| 20 | Seed 2.1 Turbo ByteDance Seed | 94 |
| 21 | Kimi K2.7 Code MoonshotAI | 96 |
| 22 | GPT 5.4 Mini OpenAI | 101 |
| 23 | Muse Glimmer 30B Meta | 109 |
| 24 | Nemotron 3 Ultra NVIDIA | 120 |
| 25 | Inkling Thinking Machines | 133 |
| 26 | Gemini 4 Argon Google | 135 |
| 27 | GPT 6 Luna Pro OpenAI | 165 |
| 28 | GPT 6 Luna OpenAI | 168 |
| 29 | Beam 1.0 501B A23B Reflection | 186 |
| 30 | Step 3.7 Flash StepFun | 188 |
| 31 | MiniMax M3.1 Flash MiniMax | 189 |
| 32 | GPT 6 Astra Pro OpenAI | 199 |
| 33 | Gemini 4 Hydrogen Google | 200 |
| 34 | GPT 6 Astra OpenAI | 201 |
| 35 | GPT 6.1 Sol Pro OpenAI | 208 |
| 36 | Grok 4.7 SpaceXAI | 212 |
| 37 | Ling 3.0 Flash inclusionAI | 212 |
| 38 | GPT 6.1 Sol OpenAI | 237 |
| 39 | Step 5 Preview StepFun | 243 |
| 40 | Gemini 4 Carbon Google | 249 |
| 41 | Claude Sonnet 5.5 Anthropic | 280 |
| 42 | Nex N2.5 Mini Nex AGI | 301 |
| 43 | Granite 4.2 8B IBM | 315 |
| 44 | DeepSeek V4 Pro 0813 DeepSeek | 317 |
| 45 | Claude Fable 5.2 Anthropic | 318 |
| 46 | Qwen3 Coder Next Qwen | 322 |
| 47 | Inkling Small Thinking Machines | 331 |
| 48 | Qwen3.7 Plus Qwen | 355 |
| 49 | Kimi K3.1 Pro MoonshotAI | 433 |
| 50 | Claude Opus 5.5 Anthropic | 457 |
| 51 | LongCat 2.0 Meituan | 501 |
| 52 | MiniMax M3 MiniMax | 527 |
| 53 | Solar Pro 4 Upstage | 570 |
| 54 | Particle 1 Particle AI | 594 |
| 55 | Ripple 65B Preview Ricursive | 651 |
| 56 | Muse Spark Open Meta | 664 |
| 57 | DeepSeek V4.1 Flash 1017 DeepSeek | 690 |
| 58 | Muse Wonder Meta | 765 |
| 59 | Ember 1 Fireworks | 873 |
| 60 | Qwen3.8 Flash Qwen | 879 |
| 61 | Muse Spark 1.3 Meta | 904 |
| 62 | Nex N2.6 Nex AGI | 923 |
| 63 | MiMo V2.6 Pro Xiaomi | 1065 |
| 64 | Qwen3.8 Omni Flash Qwen | 1102 |
| 65 | MiMo V2.6 Flash Xiaomi | 1136 |
| 66 | Muse Ember Meta | 1186 |
| 67 | Qwen3.8 Max (0902) Qwen | 1397 |
| 68 | Qwen3.8 2.4T A95B Qwen | 1522 |
| 69 | GLM 5.3 Z.ai | 1529 |
| 70 | Qwen3.8 27B Qwen | 1675 |
| 71 | Mistral Large 4 Mistral | 1763 |
| 72 | GLM 5.3 Flash Z.ai | 1899 |
Models Tested
This analysis covers 72 models from 28 companies:
View all 72 models
- Beam 1.0 501B A23B
- Claude Fable 5.2
- Claude Haiku 5.5
- Claude Opus 5.5
- Claude Sonnet 5.5
- Codestral 2508
- DeepSeek V4 Pro 0813
- DeepSeek V4.1 Flash 1017
- Ember 1
- Flint (free)
- Gemini 3.5 Flash Lite
- Gemini 3.8 Flash
- Gemini 4 Argon
- Gemini 4 Carbon
- Gemini 4 Hydrogen
- Gemma 4 26B A4B
- Gemma 4 31B
- GLM 4.7 Flash
- GLM 5.3
- GLM 5.3 Flash
- GPT 5.4 Mini
- GPT 6 Astra
- GPT 6 Astra Pro
- GPT 6 Luna
- GPT 6 Luna Pro
- GPT 6.1 Sol
- GPT 6.1 Sol Pro
- GPT 6.1 Terra
- GPT 6.1 Terra Pro
- gpt oss 120b
- Granite 4.2 8B
- Grok 4.7
- Grok Build 0.1
- Hy4
- Inkling
- Inkling Small
- Kimi K2.7 Code
- Kimi K3.1 Pro
- Ling 3.0 Flash
- LongCat 2.0
- MiMo V2.6 Flash
- MiMo V2.6 Pro
- MiniMax M3
- MiniMax M3.1 Flash
- Mistral Large 4
- Mistral Medium 3.5
- Mistral Small 4
- Muse Ember
- Muse Glimmer 30B
- Muse Spark 1.3
- Muse Spark Open
- Muse Wonder
- Nemotron 3 Ultra
- Nemotron 3.5 Lightning
- Nemotron 3.5 Super VL
- Nex N2.5 Mini
- Nex N2.6
- Nova 2 Lite
- Particle 1
- Qwen3 Coder Next
- Qwen3.7 Plus
- Qwen3.8 2.4T A95B
- Qwen3.8 27B
- Qwen3.8 Flash
- Qwen3.8 Max (0902)
- Qwen3.8 Omni Flash
- Ripple 65B Preview
- Seed 2.1 Turbo
- Solar Mini 4
- Solar Pro 4
- Step 3.7 Flash
- Step 5 Preview
Update History
November 12, 2026
Models Removed
- Nex N2.5 Pro: was Rank #7, AIMAC Debt 3.92, Cost $0.24
- Mercury 3: was Rank #35, AIMAC Debt 4.63, Cost $0.24
- Hy4 Preview: was Rank #36, AIMAC Debt 4.63, Cost $1.42
- Laguna S 2.1: was Rank #48, AIMAC Debt 5.10, Cost $0.05
- Claude Fable 5.1: was Rank #54, AIMAC Debt 6.11, Cost $42.41
- Seed 2.0 Code: was Rank #63, AIMAC Debt 13.92, Cost $1.87
Models Added
- Claude Fable 5.2: Rank #3, AIMAC Debt 3.53, Cost $53.84
- Nex N2.6: Rank #33, AIMAC Debt 5.19, Cost $0.28
- Hy4: Rank #10, AIMAC Debt 4.28, Cost $0.86
- Particle 1: Rank #27, AIMAC Debt 4.90, Cost $0.41
- Ripple 65B Preview: Rank #54, AIMAC Debt 7.43, Cost $0.29
- Gemini 4 Carbon: Rank #56, AIMAC Debt 7.82, Cost $7.22
- Gemini 4 Hydrogen: Rank #47, AIMAC Debt 6.25, Cost $5.35
- Muse Ember: Rank #62, AIMAC Debt 10.69, Cost $0.30
Notes
- The benchmark now covers 72 models from 28 companies, with 2,016 audited pages.
- Scores in this release use corrected HTML extraction and include content revealed by ordinary scrolling.
- Ranks and debts under Models Removed and in older updates predate the correction. They are not directly comparable with corrected results.
Impact
- Claude Fable 5.2 takes #3 with median AIMAC Debt of 3.53.
- GPT 5.4 Mini remains #1. Inkling Small ranks #2 and Kimi K3.1 Pro ranks #43.
- Flint, Inkling Small and GPT 5.4 Mini make up the Pareto frontier.
Older updates
October 27, 2026
Models Removed
- GPT 5.3 Codex: was Rank #2, AIMAC Debt 0.00, Cost $3.02
- GPT 5.6 Terra Pro: was Rank #19, AIMAC Debt 4.24, Cost $7.89
Models Added
- GPT 6.1 Terra Pro: Rank #23, AIMAC Debt 4.44, Cost $3.62
Notes
- The benchmark now covers 70 models from 28 companies.
- We refreshed 16 retained models across all 28 categories. Five recorded lower median debt, ten recorded higher debt, and GPT 5.4 Mini stayed at zero. The other 53 retained models keep their previous results.
- These differences compare separate runs and do not isolate changes to the models.
Impact
- GPT 5.4 Mini remains #1. With Codex retired, Kimi K3.1 Pro and Inkling Small take #2 and #3.
- Gemma 4 31B moves from #59 to #32 as median debt falls from 10.30 to 4.60.
- GPT OSS 120B moves from #8 to #34 as median debt rises from 3.85 to 4.61.
October 26, 2026
Models Removed
- GPT 6 Sol Pro: was Rank #3, AIMAC Debt 3.32, Cost $9.18
- GPT 6 Sol: was Rank #6, AIMAC Debt 3.53, Cost $3.74
- Mercury 2.5: was Rank #7, AIMAC Debt 3.71, Cost $0.03
- GPT 5.6 Terra: was Rank #18, AIMAC Debt 4.19, Cost $2.10
- Gemini 3.1 Pro Preview: was Rank #27, AIMAC Debt 4.40, Cost $4.16
- Claude Haiku 4.5: was Rank #33, AIMAC Debt 4.57, Cost $2.30
- Nemotron 3 Super: was Rank #39, AIMAC Debt 4.78, Cost $0.16
- Kimi K3: was Rank #42, AIMAC Debt 4.99, Cost $15.59
- DeepSeek V4.1 Flash: was Rank #45, AIMAC Debt 5.16, Cost $0.94
- Qwen3 Coder Plus: was Rank #53, AIMAC Debt 7.18, Cost $0.62
- Mistral Large 3 2512: was Rank #56, AIMAC Debt 8.23, Cost $0.43
- Trinity Large Thinking: was Rank #57, AIMAC Debt 8.23, Cost $0.20
- KAT Coder Pro V2.5: was Rank #59, AIMAC Debt 9.43, Cost $0.98
Models Added
- Kimi K3.1 Pro: Rank #3, AIMAC Debt 3.18, Cost $15.19
- Flint (free): Rank #6, AIMAC Debt 3.85, Cost $0.00
- Mistral Large 4: Rank #16, AIMAC Debt 4.05, Cost $10.20
- DeepSeek V4.1 Flash 1017: Rank #25, AIMAC Debt 4.40, Cost $0.27
- MiniMax M3.1 Flash: Rank #34, AIMAC Debt 4.59, Cost $0.73
- GPT 6.1 Terra: Rank #35, AIMAC Debt 4.61, Cost $1.48
- Mercury 3: Rank #36, AIMAC Debt 4.63, Cost $0.24
- Nemotron 3.5 Super VL: Rank #38, AIMAC Debt 4.64, Cost $0.15
- Step 5 Preview: Rank #40, AIMAC Debt 4.64, Cost $1.77
- Beam 1.0 501B A23B: Rank #41, AIMAC Debt 4.67, Cost $0.52
- Claude Haiku 5.5: Rank #44, AIMAC Debt 4.92, Cost $0.35
- Gemini 4 Argon: Rank #64, AIMAC Debt 13.12, Cost $5.17
- Muse Spark Open: Rank #70, AIMAC Debt 32.99, Cost $1.73
- Muse Wonder: Rank #71, AIMAC Debt 35.60, Cost $7.00
Notes
- This update adds 14 models and removes 13, bringing the benchmark to 71 models from 28 companies.
- Two AI labs join AIMAC: Recursive with its Flint coding model, and Reflection with its Beam coding and reasoning model.
Impact
- OpenAI retains #1 and #2, but Kimi K3.1 Pro takes #3 from GPT 6 Sol Pro. Flint debuts at #6.
- Mistral Large 4 reaches #16 with AIMAC Debt of 4.05, down from its predecessor's 8.23.
- Gemini 4 Argon records debt of 13.12, up from its predecessor's 4.40. Meta's Muse Spark Open and Muse Wonder enter at #70 and #71, the bottom two places.
October 3, 2026
Models Removed
- GPT 5.6 Sol: was Rank #6, AIMAC Debt 4.14, Cost $14.45
- GPT 5.6 Sol Pro: was Rank #7, AIMAC Debt 4.19, Cost $52.37
- Hy3: was Rank #11, AIMAC Debt 4.24, Cost $0.29
- Qwen3.7 Flash: was Rank #16, AIMAC Debt 4.40, Cost $0.06
- DeepSeek V4 Flash 0731: was Rank #17, AIMAC Debt 4.44, Cost $0.15
- Grok 4.6: was Rank #20, AIMAC Debt 4.55, Cost $2.11
- GPT 5.6 Luna: was Rank #24, AIMAC Debt 4.70, Cost $0.72
- Qwen3.8 Max: was Rank #25, AIMAC Debt 4.72, Cost $6.01
- Claude Sonnet 5: was Rank #28, AIMAC Debt 4.80, Cost $4.77
- Claude Fable 5: was Rank #30, AIMAC Debt 4.94, Cost $22.33
- GPT 5.6 Luna Pro: was Rank #32, AIMAC Debt 5.03, Cost $2.70
- KAT Coder Air V2.5: was Rank #36, AIMAC Debt 5.22, Cost $0.44
- MiMo V2.5: was Rank #38, AIMAC Debt 5.33, Cost $0.16
- Claude Opus 5 (Fast): was Rank #39, AIMAC Debt 5.40, Cost $44.68
- Claude Opus 5: was Rank #40, AIMAC Debt 5.65, Cost $21.51
- MiMo V2.5 Pro: was Rank #41, AIMAC Debt 5.70, Cost $0.57
- Gemini 3.7 Flash: was Rank #56, AIMAC Debt 15.18, Cost $2.70
- Muse Spark 1.2: was Rank #60, AIMAC Debt 25.56, Cost $1.94
Models Added
- GPT 6 Sol Pro: Rank #3, AIMAC Debt 3.32, Cost $9.18
- GLM 5.3 Flash: Rank #5, AIMAC Debt 3.45, Cost $0.81
- GPT 6 Sol: Rank #6, AIMAC Debt 3.53, Cost $3.74
- Mercury 2.5: Rank #7, AIMAC Debt 3.71, Cost $0.03
- Grok 4.7: Rank #8, AIMAC Debt 3.85, Cost $2.03
- Nex N2.5 Pro: Rank #10, AIMAC Debt 3.92, Cost $0.24
- GPT 6.1 Sol Pro: Rank #11, AIMAC Debt 3.97, Cost $11.17
- GPT 6 Astra Pro: Rank #12, AIMAC Debt 3.98, Cost $65.69
- Qwen3.8 Flash: Rank #13, AIMAC Debt 3.99, Cost $0.56
- GPT 6 Luna Pro: Rank #15, AIMAC Debt 4.04, Cost $0.44
- GPT 6 Astra: Rank #16, AIMAC Debt 4.04, Cost $25.92
- MiMo V2.6 Flash: Rank #17, AIMAC Debt 4.14, Cost $0.22
- GPT 6.1 Sol: Rank #21, AIMAC Debt 4.24, Cost $4.89
- Granite 4.2 8B: Rank #22, AIMAC Debt 4.32, Cost $0.04
- GPT 6 Luna: Rank #24, AIMAC Debt 4.37, Cost $0.18
- Nex N2.5 Mini: Rank #29, AIMAC Debt 4.50, Cost $0.09
- MiMo V2.6 Pro: Rank #31, AIMAC Debt 4.55, Cost $0.78
- Solar Mini 4: Rank #32, AIMAC Debt 4.55, Cost $0.05
- Ember 1: Rank #34, AIMAC Debt 4.57, Cost $11.85
- Hy4 preview: Rank #36, AIMAC Debt 4.63, Cost $1.42
- Qwen3.8 Max (0902): Rank #41, AIMAC Debt 4.94, Cost $6.60
- Claude Sonnet 5.5: Rank #43, AIMAC Debt 5.03, Cost $7.72
- DeepSeek V4.1 Flash: Rank #45, AIMAC Debt 5.16, Cost $0.94
- Claude Opus 5.5: Rank #49, AIMAC Debt 5.55, Cost $14.67
- Qwen3.8 Omni Flash: Rank #50, AIMAC Debt 5.74, Cost $0.65
- Claude Fable 5.1: Rank #51, AIMAC Debt 6.11, Cost $42.41
- Gemini 3.8 Flash: Rank #60, AIMAC Debt 9.90, Cost $2.57
- Muse Spark 1.3: Rank #67, AIMAC Debt 14.25, Cost $2.05
Notes
- OpenAI's GPT 6 and 6.1 Sol models join together, alongside the new Luna and Astra endpoints and their Pro variants.
- Anthropic, DeepSeek, Google, Qwen, SpaceXAI (formerly xAI), Xiaomi, Tencent, and Meta receive model revisions.
- IBM Granite, Inception, Nex AGI, and Fireworks join AIMAC. Solar Mini 4, GLM 5.3 Flash, and Qwen3.8 Omni Flash add tiers from existing companies.
Impact
- The benchmark grows from 60 to 70 models and from 24 to 28 companies.
- GPT 5.4 Mini and GPT 5.3 Codex retain #1 and #2. GPT 6 Sol Pro enters at #3 and GLM 5.3 Flash at #5.
- Mercury 2.5 debuts at #7 for $0.025 across 28 categories and joins the cost-versus-debt Pareto frontier.
August 22, 2026
Models Removed
- Qwen3.5 397B A17B: was Rank #5, AIMAC Debt 4.09, Cost $0.76
- Grok 4.5: was Rank #22, AIMAC Debt 4.78, Cost $2.46
- GLM 5.2: was Rank #27, AIMAC Debt 4.95, Cost $2.01
- DeepSeek V4 Pro 0423: was Rank #36, AIMAC Debt 5.43, Cost $0.71
- Gemini 3.6 Flash: was Rank #50, AIMAC Debt 14.51, Cost $4.34
Models Added
- GLM 5.3: Rank #5, AIMAC Debt 4.02, Cost $5.69
- Qwen3.8 27B: Rank #13, AIMAC Debt 4.37, Cost $4.40
- Qwen3.8 2.4T A95B: Rank #14, AIMAC Debt 4.40, Cost $7.21
- Grok 4.6: Rank #20, AIMAC Debt 4.55, Cost $2.11
- Nemotron 3.5 Lightning: Rank #22, AIMAC Debt 4.58, Cost $0.05
- DeepSeek V4 Pro 0813: Rank #26, AIMAC Debt 4.75, Cost $2.32
- Solar Pro 4: Rank #37, AIMAC Debt 5.24, Cost $0.07
- Seed 2.1 Turbo: Rank #52, AIMAC Debt 12.15, Cost $2.09
- Muse Glimmer 30B: Rank #54, AIMAC Debt 12.95, Cost $0.21
- Seed 2.0 Code: Rank #55, AIMAC Debt 13.92, Cost $1.87
- Gemini 3.7 Flash: Rank #56, AIMAC Debt 15.18, Cost $2.70
Notes
- DeepSeek V4 Pro 0813, Gemini 3.7 Flash, Qwen3.8 2.4T A95B, Grok 4.6, and GLM 5.3 replace earlier versions in their respective model lines.
- Seed 2.1 Turbo, Seed 2.0 Code, Muse Glimmer 30B, Nemotron 3.5 Lightning, Qwen3.8 27B, and Solar Pro 4 join as additional model tiers.
- ByteDance Seed and Upstage are new to AIMAC.
Impact
- The benchmark grows from 54 to 60 models and from 22 to 24 companies.
- GLM 5.3 is the standout replacement, moving Z.ai's flagship from #27 to #5 while reducing AIMAC Debt from 4.95 to 4.02.
- Qwen3.8 27B debuts at #13, narrowly ahead of the much larger Qwen3.8 2.4T A95B at #14. Both trail the retired Qwen3.5 flagship, which ranked #5.
August 6, 2026
Models Removed
- Ling 3.0 flash (free): was Rank #4, AIMAC Debt 3.92, Cost $0.00
- DeepSeek V4 Flash 0423: was Rank #22, AIMAC Debt 4.83, Cost $0.10
- Qwen3.7 Max: was Rank #44, AIMAC Debt 9.18, Cost $1.79
- Muse Spark 1.1: was Rank #53, AIMAC Debt 26.26, Cost $1.49
Models Added
- Inkling Small: Rank #3, AIMAC Debt 3.43, Cost $0.34
- Ling 3.0 flash: Rank #12, AIMAC Debt 4.32, Cost $0.03
- DeepSeek V4 Flash 0731: Rank #15, AIMAC Debt 4.44, Cost $0.15
- Qwen3.8 Max: Rank #21, AIMAC Debt 4.72, Cost $6.01
- Muse Spark 1.2: Rank #54, AIMAC Debt 25.56, Cost $1.94
Notes
- Inkling Small joins full-size Inkling as a separate model.
- The paid Ling endpoint replaces the expired free endpoint.
- DeepSeek V4 Flash 0731, Qwen3.8 Max, and Muse Spark 1.2 replace the prior versions in their lines.
Impact
- The roster grows from 53 to 54 models. Inkling Small debuts at #3, behind the two zero-debt leaders.
- Qwen3.8 Max ranks #21, up from #44 for the Qwen3.7 Max it replaces.
- Muse Spark remains last. Version 1.2 improves slightly on AIMAC Debt, 25.56 versus 26.26, while total violations rise from 781 to 1,410.
July 28, 2026
Models Removed
- GPT 5.5: was Rank #3, AIMAC Debt 3.32, Cost $12.41
- GPT 5.5 Pro: was Rank #4, AIMAC Debt 3.43, Cost $128.11
- Qwen3.6 Flash: was Rank #13, AIMAC Debt 4.67, Cost $0.58
- Claude Opus 4.8: was Rank #14, AIMAC Debt 4.78, Cost $9.33
- Claude Opus 4.8 (Fast): was Rank #22, AIMAC Debt 7.46, Cost $19.52
- Claude Sonnet 4.6: was Rank #29, AIMAC Debt 9.83, Cost $12.64
- Kimi K2.6: was Rank #33, AIMAC Debt 14.77, Cost $2.60
- KAT Coder Pro V2: was Rank #34, AIMAC Debt 14.79, Cost $0.43
- Gemini 3.5 Flash: was Rank #35, AIMAC Debt 15.00, Cost $4.83
- Grok 4.3: was Rank #36, AIMAC Debt 15.03, Cost $0.56
Models Added
- Ling 3.0 flash (free): Rank #4, AIMAC Debt 3.92, Cost $0.00
- GPT 5.6 Sol: Rank #6, AIMAC Debt 4.14, Cost $14.45
- GPT 5.6 Sol Pro: Rank #7, AIMAC Debt 4.19, Cost $52.37
- GPT 5.6 Terra: Rank #8, AIMAC Debt 4.19, Cost $2.10
- GPT 5.6 Terra Pro: Rank #10, AIMAC Debt 4.24, Cost $7.89
- Hy3: Rank #11, AIMAC Debt 4.24, Cost $0.29
- Qwen3.7 Flash: Rank #13, AIMAC Debt 4.40, Cost $0.06
- GPT 5.6 Luna: Rank #18, AIMAC Debt 4.70, Cost $0.72
- Grok 4.5: Rank #19, AIMAC Debt 4.78, Cost $2.46
- Claude Sonnet 5: Rank #21, AIMAC Debt 4.80, Cost $4.77
- Step 3.7 Flash: Rank #23, AIMAC Debt 4.83, Cost $0.60
- Kimi K3: Rank #26, AIMAC Debt 4.99, Cost $15.59
- GPT 5.6 Luna Pro: Rank #27, AIMAC Debt 5.03, Cost $2.70
- Laguna S 2.1: Rank #28, AIMAC Debt 5.10, Cost $0.05
- LongCat 2.0: Rank #30, AIMAC Debt 5.19, Cost $0.66
- KAT Coder Air V2.5: Rank #31, AIMAC Debt 5.22, Cost $0.44
- MiMo V2.5: Rank #32, AIMAC Debt 5.33, Cost $0.16
- Claude Opus 5 (Fast): Rank #33, AIMAC Debt 5.40, Cost $44.68
- Claude Opus 5: Rank #35, AIMAC Debt 5.65, Cost $21.51
- MiMo V2.5 Pro: Rank #36, AIMAC Debt 5.70, Cost $0.57
- Nemotron 3 Ultra: Rank #37, AIMAC Debt 6.73, Cost $1.62
- KAT Coder Pro V2.5: Rank #45, AIMAC Debt 9.43, Cost $0.98
- Gemini 3.6 Flash: Rank #49, AIMAC Debt 14.51, Cost $4.34
- Inkling: Rank #51, AIMAC Debt 16.91, Cost $1.83
- Gemini 3.5 Flash Lite: Rank #52, AIMAC Debt 17.81, Cost $0.87
- Muse Spark 1.1: Rank #53, AIMAC Debt 26.26, Cost $1.49
Notes
- OpenAI's GPT 5.6 family replaces GPT 5.5 and GPT 5.5 Pro and adds two lower price tiers. Luna, Terra, and Sol each ship a standard and a Pro reasoning mode at the same per-token price.
- Claude Opus 5, Claude Sonnet 5, Kimi K3, Grok 4.5, Gemini 3.6 Flash, KAT Coder Pro V2.5, and Qwen3.7 Flash replace the prior versions in their lines.
- Eight companies join the benchmark for the first time: Ant Group's inclusionAI (Ling), Tencent (Hy3), Meituan (LongCat), Thinking Machines (Inkling), Meta (Muse Spark), Poolside (Laguna), StepFun (Step), and Xiaomi (MiMo).
- Nemotron 3 Ultra joins after completing all 28 categories.
Impact
- The roster's largest expansion: 37 to 53 models. GPT 5.4 Mini keeps #1 with zero median debt for $0.95.
- The newest models are not the best models. GPT 5.6 Sol debuts at 4.14 where the GPT 5.5 it replaces scored 3.32, and at OpenAI, Anthropic, Google, Alibaba, and MoonshotAI the best result comes from an older release than the newest one.
- A free model lands near the top: Ling 3.0 flash ranks #4 with a debt of 3.92 for $0.00.
- All three GPT 5.6 Pro reasoning modes score worse than their standard versions, and Sol Pro costs $52.37 where GPT 5.5 Pro cost $128.11.
- Meta's first paid API model, Muse Spark 1.1, debuts last at #53 with 781 total violations against a field average of 448.
- 30 of 53 models cost under $1 for the full 28-category run.
June 20, 2026
Models Removed
- GLM 5.1: was Rank #35, AIMAC Debt 15.23, Cost $2.52
Models Added
- Kimi K2.7 Code: Rank #9, AIMAC Debt 4.48, Cost $1.46
- GLM 5.2: Rank #18, AIMAC Debt 4.95, Cost $2.01
Notes
- GLM 5.2 is Z.ai's latest flagship, replacing GLM 5.1.
- Kimi K2.7 Code is MoonshotAI's new coding-focused model, joining the existing Kimi K2.6.
Impact
- The roster grows from 36 to 37 models. GPT 5.4 Mini keeps #1 with zero debt for $0.95.
- Kimi K2.7 Code debuts inside the top ten at #9 (4.48 for $1.46), MoonshotAI's strongest AIMAC result.
- GLM 5.2 lands mid-pack at #18 (4.95), a marked improvement on the GLM 5.1 it replaces, which sat near the bottom at #35.
June 9, 2026
Models Removed
- Claude Opus 4.7: was Rank #16, AIMAC Debt 4.89, Cost $12.09
Models Added
- Claude Fable 5: Rank #16, AIMAC Debt 4.94, Cost $22.33
Notes
- Anthropic released Claude Fable 5 on June 9, 2026, the most capable model it has made generally available. It is the public version of Claude Mythos 5, the same model wrapped in new safety classifiers that route cybersecurity, biology, and chemistry requests to Claude Opus 4.8.
- Claude Opus 4.7 was added in the June 5 update as a one-time catch-up for a missed release cycle and is now retired.
Impact
- Anthropic's most capable public model is its third-best here, behind Claude Haiku 4.5 (#10) and Claude Opus 4.8 (#13), at the highest cost of any Anthropic model on the board ($22.33).
- Fable 5 lands at #16 with a debt of 4.94, slightly behind the Opus 4.7 (4.89) that retires in the same update.
- The roster holds at 36 models. GPT 5.4 Mini keeps #1 with zero debt for $0.95.
June 5, 2026
Models Removed
- GPT 5.4: was Rank #3, AIMAC Debt 0.00, Cost $4.48
- GPT 5.4 Pro: was Rank #4, AIMAC Debt 1.00, Cost $212.75
- Trinity Large Preview (free): was Rank #5, AIMAC Debt 3.98, Cost $0.00
- o3: was Rank #6, AIMAC Debt 4.02, Cost $1.13
- Qwen3 Max: was Rank #7, AIMAC Debt 4.14, Cost $1.07
- Kimi K2 Thinking: was Rank #12, AIMAC Debt 4.54, Cost $0.82
- o4 Mini: was Rank #13, AIMAC Debt 4.58, Cost $0.74
- Grok 4.1 Fast: was Rank #14, AIMAC Debt 4.61, Cost $0.08
- Mistral Medium 3.1: was Rank #15, AIMAC Debt 4.70, Cost $0.45
- Olmo 3.1 32B Instruct: was Rank #16, AIMAC Debt 4.80, Cost $0.12
- Nemotron 3 Super (free): was Rank #17, AIMAC Debt 4.82, Cost $0.00
- Kimi K2.5: was Rank #19, AIMAC Debt 5.12, Cost $1.07
- MiniMax M2.7: was Rank #20, AIMAC Debt 5.34, Cost $1.28
- Qwen3.6 Plus: was Rank #22, AIMAC Debt 5.41, Cost $0.99
- Claude Opus 4.6 (Fast): was Rank #23, AIMAC Debt 5.94, Cost $112.18
- Qwen3 Max Thinking: was Rank #24, AIMAC Debt 6.00, Cost $1.11
- Gemini 3 Flash Preview: was Rank #25, AIMAC Debt 6.84, Cost $0.66
- Claude Opus 4.6: was Rank #26, AIMAC Debt 6.90, Cost $18.34
- DeepSeek V3.2 Speciale: was Rank #28, AIMAC Debt 7.21, Cost $0.20
- DeepSeek V3.2: was Rank #30, AIMAC Debt 8.18, Cost $0.09
- Qwen3 Coder Flash: was Rank #31, AIMAC Debt 8.20, Cost $0.31
- Devstral 2 2512: was Rank #34, AIMAC Debt 9.01, Cost $0.13
- R1 0528: was Rank #37, AIMAC Debt 10.17, Cost $0.66
- Grok 4.20: was Rank #38, AIMAC Debt 11.16, Cost $2.07
- Qwen3.5 Flash: was Rank #39, AIMAC Debt 11.37, Cost $0.09
Models Added
- GPT 5.5: Rank #3, AIMAC Debt 3.32, Cost $12.41
- GPT 5.5 Pro: Rank #4, AIMAC Debt 3.43, Cost $128.11
- Qwen3.7 Plus: Rank #11, AIMAC Debt 4.64, Cost $0.61
- Qwen3.6 Flash: Rank #12, AIMAC Debt 4.67, Cost $0.58
- Claude Opus 4.8: Rank #13, AIMAC Debt 4.775, Cost $9.33
- Nemotron 3 Super: Rank #14, AIMAC Debt 4.778, Cost $0.16
- DeepSeek V4 Flash: Rank #15, AIMAC Debt 4.83, Cost $0.10
- Claude Opus 4.7: Rank #16, AIMAC Debt 4.89, Cost $12.09
- MiniMax M3: Rank #17, AIMAC Debt 5.16, Cost $0.73
- DeepSeek V4 Pro: Rank #18, AIMAC Debt 5.43, Cost $0.71
- Claude Opus 4.8 (Fast): Rank #20, AIMAC Debt 7.46, Cost $19.52
- Mistral Medium 3.5: Rank #21, AIMAC Debt 8.16, Cost $1.65
- Qwen3.7 Max: Rank #26, AIMAC Debt 9.18, Cost $1.79
- Gemma 4 26B A4B: Rank #29, AIMAC Debt 11.15, Cost $0.06
- Kimi K2.6: Rank #31, AIMAC Debt 14.77, Cost $2.60
- Gemini 3.5 Flash: Rank #33, AIMAC Debt 15.00, Cost $4.83
- Grok 4.3: Rank #34, AIMAC Debt 15.03, Cost $0.56
- Grok Build 0.1: Rank #36, AIMAC Debt 16.42, Cost $1.24
Notes
- This update refreshes AIMAC against the current roster of 36 models, replacing retired, superseded, or unavailable endpoints from the April leaderboard.
- OpenAI still leads the benchmark, but the order changed: GPT 5.4 Mini is now #1, GPT 5.3 Codex is #2, and GPT 5.5 and GPT 5.5 Pro replace the 5.4 mainline/pro slots.
- Anthropic's Opus line is refreshed with Opus 4.7, Opus 4.8, and Opus 4.8 Fast. Haiku remains Anthropic's strongest AIMAC performer.
- Qwen, DeepSeek, Google/Gemini, Mistral, MiniMax, Kimi, NVIDIA, and Grok all move to newer endpoints.
Impact
- Two models now achieve zero median AIMAC Debt: GPT 5.4 Mini and GPT 5.3 Codex.
- The value story gets stronger: gpt oss 120b ranks #5 for $0.09, and 21 of 36 models cost under $1.
- The top five is now all OpenAI, including the open-weight gpt oss 120b.
April 9, 2026
Models Removed
- GLM 5: was Rank #5, AIMAC Debt 2.66, Cost $2.03
- GPT 5.1 Codex Mini: was Rank #6, AIMAC Debt 3.78, Cost $0.39
- Qwen3.6 Plus Preview (free): was Rank #12, AIMAC Debt 4.44, Cost $0.00
Models Added
- Qwen3.6 Plus: Rank #22, AIMAC Debt 5.41, Cost $0.99
- Claude Opus 4.6 (Fast): Rank #23, AIMAC Debt 5.94, Cost $112.18
- Gemma 4 31B: Rank #40, AIMAC Debt 12.59, Cost $0.08
- GLM 5.1: Rank #42, AIMAC Debt 16.38, Cost $2.47
Notes
- GLM 5.1 replaces GLM 5 as Z.AI's latest flagship. GLM 5.1 was retrained for coding/agentic tasks and achieved SOTA on SWE-Bench Pro, but dropped from #5 to #42 on accessibility.
- GPT 5.1 Codex Mini retired as OpenAI consolidates around the 5.3/5.4 generation.
- Qwen3.6 Plus is the GA release of the preview. Free access ends; the paid model costs $0.99.
- Claude Opus 4.6 (Fast) is Anthropic's fourth model on the benchmark, filling the premium-fast slot.
- Gemma 4 31B is Google's first open-weight model to pass the 10KB HTML threshold.
Impact
- GLM 5 to 5.1 is a 37-rank plunge (#5 to #42)
- Power shift in the Top 3 Winners: Z.AI exits as its flagship craters; Alibaba/Qwen takes its place with Qwen3 Max at #7 and eight models spread across the leaderboard.
- Trinity Large Preview (free) climbs to #5, the first $0 model to crack the top five.
April 1, 2026
Models Added
- Trinity Large Thinking (Arcee AI): Rank #30, AIMAC Debt 7.97, Cost $0.25
Notes
- Arcee AI's second model on the benchmark, alongside Trinity Large Preview (free) at #7.
Impact
- Arcee AI now has two models on the benchmark: Trinity Large Preview (free) at #7 and Trinity Large Thinking at #30.
March 31, 2026
Models Removed
- Grok 4.20 Beta: was Rank #39, AIMAC Debt 12.53, Cost $2.09
Models Added
- Grok 4.20: Rank #38, AIMAC Debt 11.16, Cost $2.07
Notes
- Grok 4.20 GA supersedes the Beta release.
- Updated WebAIM Million comparison data from 2025 to 2026 following the new report (published March 30, 2026). The 2026 report reversed six years of gradual improvement: errors per page jumped 10% and 95.9% of sites now fail basic checks.
Impact
- xAI's flagship improves slightly (debt 12.53 to 11.16), gaining one rank from #39 to #38.
- Qwen3.5 Flash shifts from #38 to #39. All other rankings are unchanged.
March 30, 2026
Models Removed
- Qwen3.5 Plus 2026 02 15: was Rank #24, AIMAC Debt 5.73, Cost $0.54
Models Added
- Qwen3.6 Plus Preview (free): Rank #12, AIMAC Debt 4.44, Cost $0.00
Notes
- Qwen3.6 Plus Preview supersedes Qwen3.5 Plus.
- The count of models under $1 remains 27 (both models are under $1).
Impact
- Alibaba's Qwen Plus line improves from #24 to #12, a 12-spot jump.
- Ranks 12-23 each shift down by one. Top 11 and ranks 25-41 are unchanged.
March 28, 2026
Models Removed
- KAT Coder Pro V1: was Rank #12, AIMAC Debt 4.46, Cost $0.22
Models Added
- KAT Coder Pro V2: Rank #40, AIMAC Debt 13.19, Cost $0.44
Notes
- KAT Coder Pro V2 supersedes V1. Score regressed sharply from 4.46 to 13.19, rank dropping from #12 to #40. Cost doubled from $0.22 to $0.44.
- The count of models under $1 remains 27 (both V1 and V2 are under $1).
Impact
- KwaIPilot drops from the upper tier to second-to-last. V1 was a standout budget pick; V2 is one of the weakest models on the benchmark.
- Ranks 13-39 each shift up by one. Top 11 and last place are unchanged.
March 22, 2026
Models Removed
- MiniMax M2.5: was Rank #9, AIMAC Debt 4.04, Cost $0.25
Models Added
- MiniMax M2.7: Rank #23, AIMAC Debt 5.34, Cost $1.28
Notes
- MiniMax M2.7 supersedes M2.5. Score regressed from 4.04 to 5.34, rank dropping from #9 to #23. Cost increased from $0.25 to $1.28.
- The count of models under $1 drops from 28 to 27 because M2.7 costs $1.28 (M2.5 was $0.25).
Impact
- MiniMax falls out of the Top 10 after its M2.5 held #9. The upgrade traded accessibility for other capabilities.
- Top 8 and bottom 18 ranks are unchanged. Only ranks 9-22 shift up by one.
March 17, 2026
Models Removed
- GPT 5.2 Pro: was Rank #3, AIMAC Debt 2.77, Cost $95.45
- GPT 5.2: was Rank #4, AIMAC Debt 3.05, Cost $6.63
- Gemini 2.5 Flash Lite: was Rank #23, AIMAC Debt 5.42, Cost $0.09
- GPT 5 Mini: was Rank #30, AIMAC Debt 7.62, Cost $0.60
- Mistral Small 3.2 24B: was Rank #35, AIMAC Debt 8.48, Cost $0.03
Models Added
- GPT 5.4 Mini: Rank #2, AIMAC Debt 0.00, Cost $0.89
- GPT 5.4: Rank #3, AIMAC Debt 0.00, Cost $4.48
- GPT 5.4 Pro: Rank #4, AIMAC Debt 1.00, Cost $212.75
- Nemotron 3 Super (free): Rank #21, AIMAC Debt 4.82, Cost $0.00
- Qwen3.5 Flash: Rank #39, AIMAC Debt 11.37, Cost $0.09
- Grok 4.20 Beta: Rank #40, AIMAC Debt 12.53, Cost $2.09
- Mistral Small 4: Rank #41, AIMAC Debt 16.96, Cost $0.18
Notes
- GPT 5.4 Mini achieves a median AIMAC Debt of 0.00 at $0.89, the second model to reach zero debt.
- GPT 5.4 and GPT 5.4 Pro replace their 5.2 predecessors as the latest versions in each slot. GPT 5.4 Pro costs $212.75, more than double the $95.45 that GPT 5.2 Pro cost, making it the most expensive model on the benchmark by a wide margin.
- Gemini 2.5 Flash Lite is removed. Google's replacement (Gemini 3.1 Flash Lite Preview) fails the 10KB minimum HTML size requirement, so the Flash Lite slot goes away.
- Mistral Small 4 (119B) replaces Small 3.2 24B as Mistral's latest Small release, but regresses from #35 (debt 8.48) to dead last at #41 (debt 16.96).
- Grok 4.20 Beta is xAI's new flagship but lands at #40, while xAI's own Grok 4.1 Fast sits at #18.
Impact
- GPT 5.4 Mini ($0.89) is the value headline: zero accessibility debt for under a dollar.
- Three OpenAI models now hold spots #2 through #4, with the existing GPT 5.3 Codex still at #1.
February 25, 2026
Models Removed
- GPT 5.2 Codex: was Rank #3, AIMAC Debt 3.05, Cost $1.94
- Gemini 3 Pro Preview: was Rank #39, AIMAC Debt 10.65, Cost $3.35
Models Added
- GPT 5.3 Codex: Rank #1, AIMAC Debt 0.00, Cost $3.02
- Gemini 3.1 Pro Preview: Rank #11, AIMAC Debt 4.40, Cost $4.16
Notes
- GPT 5.3 Codex replaces GPT 5.2 Codex per version policy. It achieves a median AIMAC Debt of 0.00 with just 20 total violations across 28 categories, taking #1 from GLM 5.
- Gemini 3.1 Pro Preview replaces Gemini 3 Pro Preview per version policy. A dramatic improvement from #39 (debt 10.65) to #11 (debt 4.40).
Impact
- OpenAI takes back #1 with the first model to achieve a median AIMAC Debt of 0.00.
- Google goes from dead last to #11, the largest single-update improvement we have tracked.
February 17, 2026
Models Removed
- Aurora Alpha: was Rank #9, AIMAC Debt 4.05, Cost $0.00
- Claude Sonnet 4.5: was Rank #19, AIMAC Debt 4.78, Cost $6.20
Models Added
- Claude Sonnet 4.6: Rank #37, AIMAC Debt 9.83, Cost $12.64
- OLMo 3.1 32B Instruct: Rank #18, AIMAC Debt 4.80, Cost $0.12
- Qwen3.5 Plus 2026 02 15: Rank #23, AIMAC Debt 5.73, Cost $0.54
- Qwen3.5 397B A17B: Rank #36, AIMAC Debt 9.16, Cost $0.87
Notes
- Claude Sonnet 4.6 replaces Sonnet 4.5 per version policy; Sonnet regresses from #19 (Debt 4.78) to #37 (Debt 9.83) in this collection.
- Aurora Alpha was removed due to a 10KB minimum HTML threshold failure (one or more categories fell below 10KB).
- OLMo 3.1 32B Instruct adds an open-weight model from AllenAI (Allen Institute for AI), a US-based non-profit AI research lab.
- Two Qwen 3.5 models expand Qwen coverage with additional product lines.
Impact
- The production leaderboard expands from 37 to 39 models.
- #1 remains GLM 5 (AIMAC Debt 2.66).
- 27 of 39 models cost under $1.
February 12, 2026
Models Removed
- MiniMax M2.1: was Rank #18, AIMAC Debt 4.74, Cost $0.28
Models Added
- MiniMax M2.5: Rank #8, AIMAC Debt 4.04, Cost $0.25
Notes
- MiniMax M2.5 supersedes M2.1. Score improved from 4.74 to 4.04, rank jumping from #18 to #8.
Impact
- MiniMax M2.5 returns to the Top 10 with this entry.
February 11, 2026
Models Removed
- MiniMax M1: was Rank #5, AIMAC Debt 3.78, Cost $0.82
- Kimi K2 0905: was Rank #9, AIMAC Debt 4.39, Cost $0.54
- GLM 4.7: was Rank #13, AIMAC Debt 4.51, Cost $0.44
- Qwen3 Coder 480B A35B: was Rank #22, AIMAC Debt 6.01, Cost $0.33
- Claude Opus 4.5: was Rank #25, AIMAC Debt 7.06, Cost $19.92
- Qwen3 235B A22B Instruct 2507: was Rank #27, AIMAC Debt 7.54, Cost $0.26
- R1: was Rank #29, AIMAC Debt 8.08, Cost $0.70
- GLM 4.5 Air: was Rank #36, AIMAC Debt 9.33, Cost $0.33
Models Added
- GLM 5: Rank #1, AIMAC Debt 2.66, Cost $2.03
- Trinity Large Preview: Rank #6, AIMAC Debt 3.98, Cost $0.00
- Aurora Alpha: Rank #8, AIMAC Debt 4.05, Cost $0.00
- Qwen3 Coder Next: Rank #20, AIMAC Debt 4.99, Cost $0.41
- Kimi K2.5: Rank #21, AIMAC Debt 5.12, Cost $1.07
- Qwen3 Max Thinking: Rank #24, AIMAC Debt 6.00, Cost $1.11
- Claude Opus 4.6: Rank #26, AIMAC Debt 6.90, Cost $18.34
- R1 0528: Rank #36, AIMAC Debt 10.17, Cost $0.66
Notes
- GLM 5 by Z.ai takes 1st place, dethroning GPT 5.2 Pro. It is MIT-licensed open-source at $2.03 total, compared to GPT 5.2 Pro's $95.45.
- Trinity Large Preview by Arcee AI enters at #6 for free. It is a US-based open-source model.
- GLM 4.7 and GLM 4.5 Air are both superseded by GLM 5.
- Claude Opus 4.6 replaces Opus 4.5. Marginally better debt (6.90 vs 7.06) but ranks #26 due to new entrants.
- R1 0528 replaces R1. Cheaper with larger context, but scored worse on accessibility (10.17 vs 8.08).
- MiniMax M1 superseded by M2.1.
- Kimi K2 0905 superseded by K2.5.
- Qwen3 235B A22B Instruct 2507 removed. Qwen3 Coder 480B A35B trimmed in favor of Coder Next and Coder Plus variants.
Impact
- Open-source models now lead the leaderboard: GLM 5 at #1 and Trinity Large Preview at #6.
- OpenAI retains four of the top five spots (#2 through #5) but loses the crown.
January 19, 2026
Models Removed
- GPT 5.1 Codex: was Rank #3, AIMAC Debt 3.53, Cost $1.72
- KAT Coder Pro V1 (free): was Rank #14, AIMAC Debt 4.55, Cost $0.00
Models Added
- GPT 5.2 Codex: Rank #2, AIMAC Debt 3.05, Cost $1.94
- KAT Coder Pro V1: Rank #10, AIMAC Debt 4.46, Cost $0.22
- GLM 4.7 Flash: Rank #20, AIMAC Debt 5.37, Cost $0.11
Notes
- GPT 5.2 Codex succeeds GPT 5.1 Codex in our benchmark. We test the latest version of each model line.
- KAT Coder Pro V1 replaces the free tier, which OpenRouter deprecated on January 12.
Impact
- KAT Coder Pro V1 entering at #10 pushed Claude Haiku 4.5 to #11.
Acknowledgments
We are grateful to ServiceNow for their partnership, without which AIMAC would not be possible. This project was inspired by the WebAIM Million report. Note: although the Foundation regularly partners with WebAIM on projects such as the Global Digital Accessibility Salary Survey (GDASS), we did not happen to consult with them yet on this project. Any errors in this report are our own. We must acknowledge Deque for open sourcing axe-core, the engine powering our testing, and Microsoft for Playwright, which powers our browser automation. Microsoft are also partners in AIMAC's next benchmark, which will be accompanied by a research paper written by Yumeng Ma. We appreciate the collaboration, advice and feedback from Ed Summers, Jennifer Mankoff, Aaron Gustafson, Charlie Triplett, AnnMarie Dittell, Venkatesh Potluri, Jacob Wobbrock and Mary Bellard.
Methodology
What is AIMAC?
When you ask an LLM to build a web page, how accessible is the HTML it generates? AIMAC answers that question.
We prompt 72 models to generate pages across 28 categories with no accessibility guidance. Then we run axe-core, the accessibility testing engine used by Microsoft, Google, and most major tech companies, to count violations against WCAG 2.2 Level AA, the current version of the Web Content Accessibility Guidelines. Lower scores mean fewer problems.
The result is an apples-to-apples comparison of how well models handle accessibility without being told to.
Understanding "AIMAC Debt"
The AIMAC Debt measures automated accessibility violations. Lower is better.
What the numbers mean
- 0.00 is the lowest possible debt. A model's median of 0.00 means that at least 15 of its 28 pages had no critical or serious violations detected.
- Lower single-digit scores generally mean the model generates relatively clean HTML
- Higher scores mean more severe and/or more numerous violations; double-digit scores indicate substantial accessibility work is needed
Low contrast text accounts for 90.3% of detected errors in this leaderboard. Other errors include empty buttons, missing form labels and misused ARIA, the HTML attributes that help screen readers understand page structure.
How AIMAC Debt is calculated
- Critical violations (missing form labels, empty buttons): 5 points each
- Serious violations (insufficient color contrast): 2 points each
- Duplicate violations are dampened to avoid over-counting (details below)
We report the median debt across all 28 categories to avoid outliers.
Technical details: Dampening formula
For those interested in the math: we use logarithmic dampening for duplicate violations of the same issue type on a page.
Formula: score = base_weight × (1 + k × log₂(N))
Where:
N= number of duplicate violationsk= dampening factor (0.75 critical, 0.5 serious, 0.33 color-contrast)base_weight= 5 critical, 2 serious
This ensures 100 duplicates from one bad CSS rule don't count as heavily as 100 separate issues, while still encouraging comprehensive fixes.
How Reliable Are These Rankings?
Each rank summarizes 28 category results. Models can perform differently across page types, so check category-specific results on the detail pages when choosing a model for your work.
Excluded Models
Pages under 10KB don't contain enough HTML to fairly test for accessibility mistakes. A 5KB page with zero violations isn't "better" than a 50KB page with three. They're solving different problems. We exclude models that produce minimal output to keep comparisons fair.
Why This Scoring System?
Our scoring reflects real-world impact:
- Critical violations (5 points vs 2 for serious): Empty buttons or missing labels completely block screen reader users
- Duplicate dampening: One bad CSS color causing 50 violations doesn't overwhelm the score
- Extra color-contrast dampening: Repeated contrast failures get less weight than the same number of other serious violations
We apply the same weights and dampening factors to every model.
Scope of Automated Testing
Axe-core catches many issues: color contrast, missing labels, empty buttons, ARIA errors.
What automated testing can't catch: keyboard navigation problems, screen reader flow issues, real-world usability. Lower AIMAC Debt means a cleaner starting point, not a guarantee of perfect accessibility. Manual testing is still needed.
Preventing Benchmark Gaming
AIMAC's prompts are public. You can inspect exactly what we ask models to generate.
To prevent AI companies from training on specific prompt patterns, we use prompt randomization. Each category prompt contains example lists (navigation links, section themes) randomly selected from larger pools at runtime.
With current fragment pools, this yields hundreds of billions of prompt variants per category (tens of trillions across all 28 categories). Memorization is computationally infeasible.
The core instructions stay constant; only stylistic examples vary. AIMAC Debt reflects genuine capability, not prompt memorization.
Understanding the Total Cost
The Total Cost column shows the API cost in USD of the 28 saved pages behind each model's result. It excludes failed attempts and retries, and it is not a live price quote.
For Benchmark Authors
While preparing to publish, we hit some visualization challenges that led us to consider Datasette, Simon Willison's tool for exploring and publishing data. We haven't implemented it yet, but the problems we encountered seem common to benchmarks, so we're sharing what we learned.
Future explorations: Datasette, Pareto and Slope Charts
Why publish your data?
Benchmark authors face a perplexing set of tradeoffs. Which models to include? How many prompts to test? How many variants? Worst of all, we can't know which version of a model we're testing because models get updated without public versioning. Companies change system prompts, infrastructure, or other API elements without warning. No benchmark will ever be truly repeatable. Publishing your data with an interactive website is a service to everyone, allowing the hive mind to improve the benchmark by highlighting gaps.
Datasette with its 154 plugins could let us embed an interactive database viewer directly on this page. It doesn't yet have Pareto or slope chart plugins, but general visualization plugins exist (datasette-vega, datasette-plot). Any interactive charting would need careful accessibility testing, which is why we deferred it.
Sure, it's a great model, but is it Pareto optimal?
AI models are expensive. Benchmarks need a way to measure quality per dollar. Pareto Front charts are popular because they plot cost on one axis and quality on the other, quickly showing which models offer the best value.
Naming matters here. We originally called our metric "AIMAC Score," but users expect higher scores to be better. Thanks to an insight by Charlie Triplett, we renamed it to "AIMAC Debt." People intuitively understand that you want debt to be lower.
Even with better naming, the Pareto chart still forces a choice between two kinds of unintuitiveness. You can leave the axes semantically honest (lower = better) and accept that the optimal quadrant is bottom-left. Or you can invert both axes so "up and to the right" means better, at the cost of making the axis directions themselves counterintuitive. Neither is great. An interactive chart that lets users toggle between views would help.
Slope Charts
Slope charts offer another way to visualize the cost vs. quality tradeoff. They plot each model's quality rank on the left and cost rank on the right, then draw a line between them. A flat or rising line means the model delivers good value: its cost rank matches or beats its quality rank. A steep drop means you're paying a premium for that quality. Pareto-optimal models are highlighted.
We removed the slope chart from this iteration because with so many models, effectiveness drops, especially when costs cluster at the low end as ours do. Here's a mockup showing what it looked like when the distribution told the story well (note that this chart pre-dated our renaming of AIMAC Score to AIMAC Debt):

Sample slope chart mockup. Slope charts can make the cost versus debt tradeoff easier to scan when the distribution is clear.
For Model Providers
Most benchmarks are simply focused on ranking models. Our goal is that every model achieve a perfect score.
When AI generates accessible code by default, people with disabilities are no longer locked out of digital technology. A future where every model aces this benchmark means an internet that works for everyone. To be frank, as much effort as we put into the first iteration of this benchmark, achieving a perfect score on an automated metric that is easy to lint and produce synthetic data for is table stakes. However, we decided to start here because the models aren't even doing this minimum step.
How to Ace the Benchmark
Test the way we test. We run axe-core against rendered HTML in a real browser. Static linters won't catch everything. Color contrast, for example, requires computing actual styles from cascading CSS. Playwright's accessibility testing guide covers the setup.
The AIMAC repository has our test prompts and scoring code.
Questions? joe@gaad.foundation
Press
AIMAC has been featured in publications, podcasts, conference talks, and industry roundups. Selected coverage highlights:
Launch Coverage
- VKTR - The Open‑Source AI Accessibility Checker Holding LLMs Accountable by Michelle Hawley
- The AI Economy - Can Your AI Code for Everyone? by Ken Yeung
- Curb Cuts - GAAD Foundation, ServiceNow Announce AI Model Accessibility Checker API by Steven Aquino
- Access Adventure - GAAD Foundation Launches AI Accessibility Checker with ServiceNow
- NYSE TV - Joe Devon Joins NYSE TV Live
- AMI Media - The Pulse - Global Accessibility Awareness Day with Joe Devon
Conference Talks
- A11y Camp Australia - Joe Devon Keynote: Raising the Bar: AIMAC and the Future of Accessible AI Development (October 2025, archived page)
- Sight Tech Global - Holding AI Accountable: Benchmarking Accessibility with AIMAC (November 2025)
Upcoming
- All Things Open 2026 - Open Source Accessibility Summit keynote by Joe Devon. Raleigh, NC (October 19, 2026)
- ASSETS 2026 - Prompt and Circumstance: Evaluating Accessibility in LLM-Generated HTML Form Components (PACE), paper by Yumeng Ma, Joe Devon, and co-authors. Porto, Portugal (October 27, 2026)
Podcasts
- AI Engineering Podcast - Generative AI Meets Accessibility: Benchmarks, Breakthroughs, and Blind Spots with Joe Devon by Tobias Macey (January 5, 2026)
- FUTUREPROOF Podcast - AI Is Scaling Fast - Accessibility Isn't. Here's How We Fix That. by Jeremy Goldman (January 6, 2026)
- Daily Tech News Show - CES 2026 - OpenAI Makes the Most Accessible Code (for an LLM) by Tom Merritt (January 7, 2026)
- Investing in Accessibility Podcast - Are ChatGPT, Claude, and Gemini Accessible? A Revealing Conversation with Joe Devon by Kelvin Crosby and Chris Maher (January 26, 2026)
- Double Tap Podcast - AI Accessibility Benchmarks: Holding Models Accountable in 2026 by Steven Scott and Shaun Preece (February 2, 2026)
- Accessibility and Gen AI Podcast - Ep 14 - AIMAC: The AI Model Accessibility Checker with Eamon McErlean, Joe Devon, and a screen reader demo by Jennison Asuncion (February 16, 2026)
- AI: Voice or Victim Podcast - AI and Accessibility: Are We Building a More Inclusive Future or Leaving People Behind? (February 18, 2026)
- PureLogics Pulse Podcast - Understanding AI in 2026: Reality and Lessons for C-Level Leaders (March 4, 2026)
- Government Video Podcast - Global Accessibility Awareness Day: How AI Is Shaping What Comes Next by Michelle Alimoradi (May 14, 2026)
- DATAVERSITY - My Career in Data Season 4 Episode 09: Joe Devon, Chair of the GAAD Foundation and Co-founder of Global Accessibility Awareness Day (June 3, 2026)
Articles & Interviews
- The New Stack - Does LLM Write Performant Code? Study Says No by Loraine Lawson (May 17, 2025)
- Forkable - Microsoft's (and Linux's) big week in open source by Paul Sawers (May 24, 2025)
- Forbes - Does AI Make Technology More Accessible Or Widen Digital Inequalities? by Gus Alexiou (June 1, 2025)
- Crip Life - Championing Digital Inclusion: The Story Behind GAAD by Emma Purcell
- Curb Cuts - AIMAC Founders Joe Devon, Eamon McErlean Talk First Round of Results in New Interview by Steven Aquino (January 23, 2026)
- Accessibility for All Magazine - OpenAI Dominates, Google Disappoints in New AI Coding Model Accessibility Benchmark (February 23, 2026)
- The AI Innovator - The 1.3 Billion-Person Market AI Can't Afford to Ignore by Joe Devon (April 14, 2026)
- Forbes - Artificial Intelligence Has One Chance To Get Accessibility Right by Keely Cat-Wells (May 3, 2026)
- Executive's Diary - Architecting Equality: Joe Devon, AI, and the New Era of Digital Craftsmanship by Momina Ghafoor (May 4, 2026)
- Curb Cuts - GAAD Founders Talk Accessibility in new Interview by Steven Aquino (June 8, 2026)
- PN Magazine - AI For Everyone by Brittany Martin (August 15, 2026)
Industry Mentions
- Deque - Accessibility reads: Thursday, May 29 by Matthew Luken
- Trend Hunter - GAAD Foundation Partners with ServiceNow to Enhance Accessibility by Kalin Ned (May 31, 2025)
- Lumar - Digital Accessibility News June 2025 (June 2025)
- Vispero - The State of Accessibility Episode 11: AI's Disruption on Design, Part 2 (July 2025)
- QualityLogic - Accessibility Industry Update (October 2025)
- ServiceNow Community - AIMAC: Raising the Bar for Accessible AI (November 21, 2025)
- OZeWAI - Weekly Reading List (January 26, 2026)
- ServiceNow Community - GAAD 2026 Fireside Chat: AI, Accessibility, and What It Takes to Get It Right (May 26, 2026)
- WebAIM - July 2026 Newsletter
- Deque - New survey and report from Deque Systems shows volume of AI-generated code is significantly increasing "accessibility debt" risk (July 23, 2026)
- Evinced - AIMAC Tests AI Models with axe-core for Accessibility (LinkedIn post, September 14, 2026)